One-sentence definition
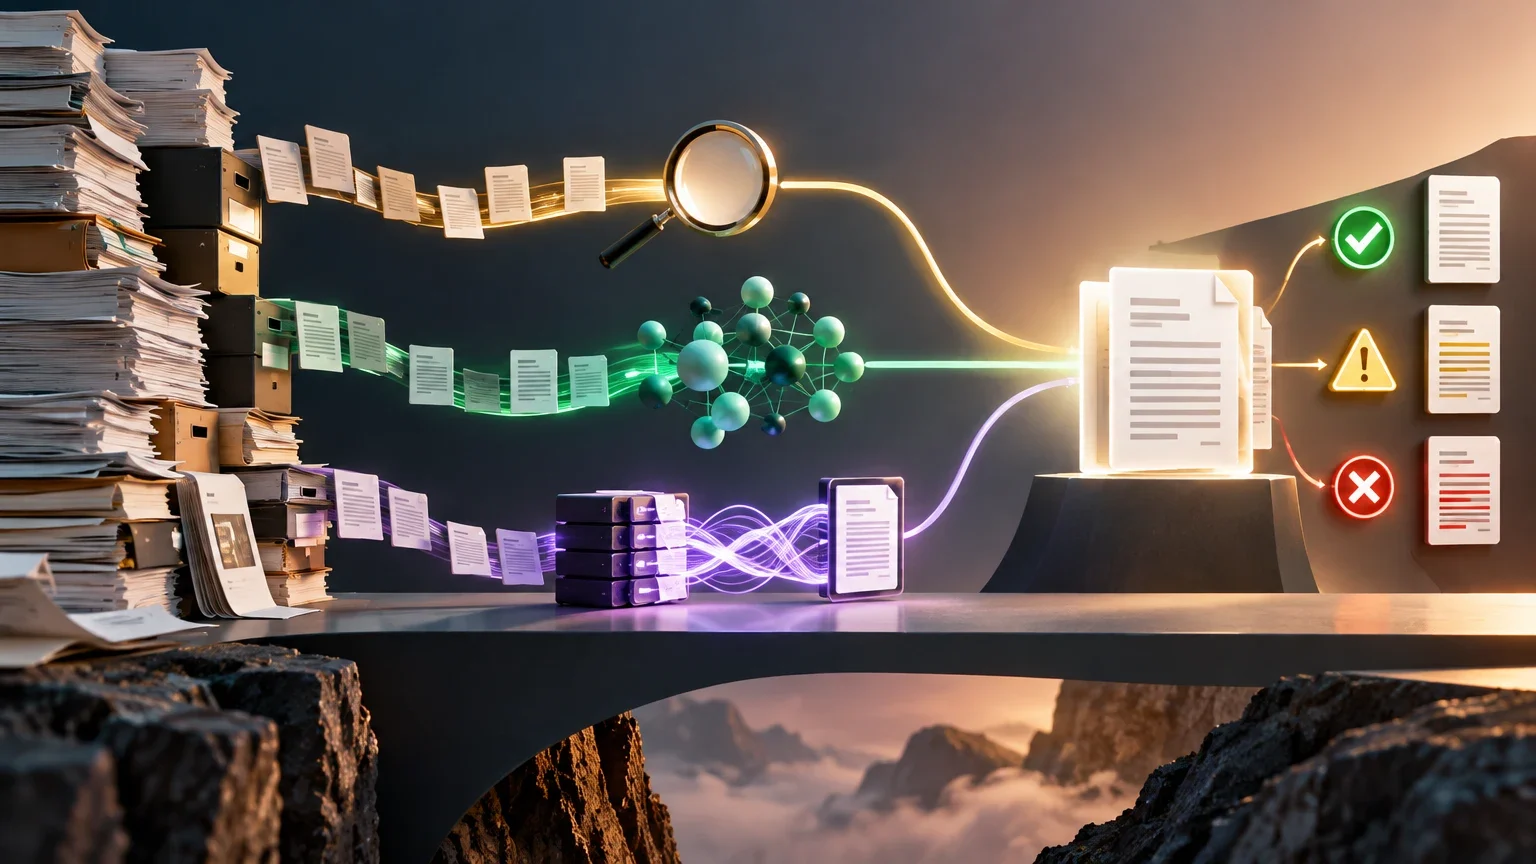
Segunda etapa que vuelve a puntuar candidatos recuperados para colocar primero los más relevantes para la consulta.
Definition: Reranking as a second scoring stage
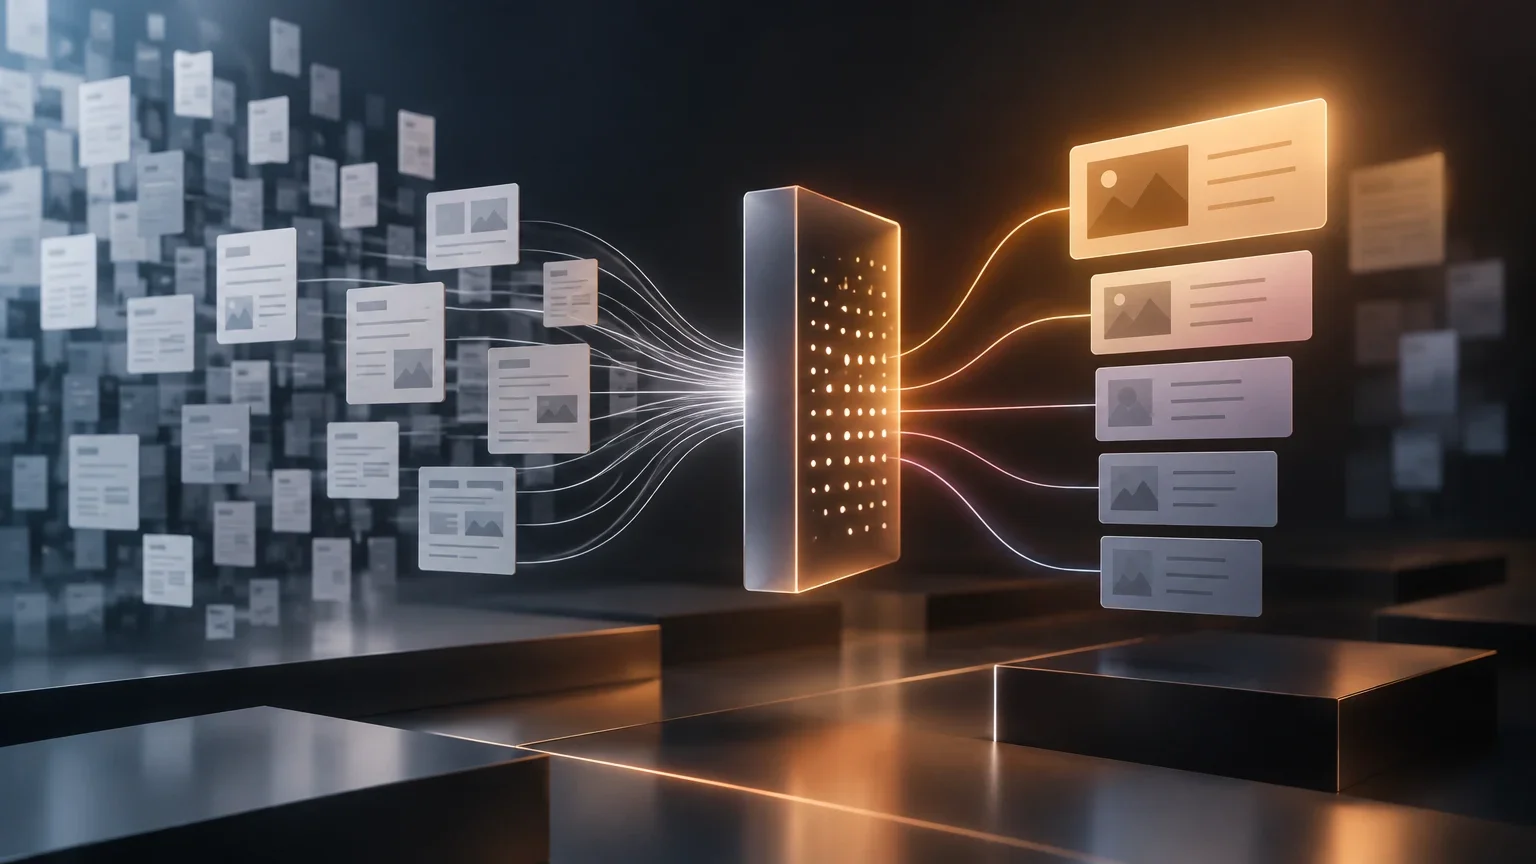
Reranking is a retrieval technique that scores and reorders documents after an initial search. The first stage is often designed to find a broad set of potentially relevant candidates, favoring recall. Reranking then examines that candidate set and moves the documents judged most relevant closer to the top, aiming to improve precision among the results that will actually be used.
In retrieval-augmented generation (RAG), that distinction matters because a language model has a finite context window and the quality of its answer depends partly on the information supplied to it. If the initial retrieval returns loosely related or noisy documents, those can distract from useful evidence. A reranker evaluates each candidate in relation to the user’s specific query and can help select a more focused set for the next stage. It cannot recover a relevant document that the first-stage search did not retrieve.
How it works: bi-encoders and cross-encoders
Many first-stage systems use bi-encoders, including embedding models. They encode a query and each document separately. Document embeddings can be computed and stored ahead of time, so a search system can compare a query vector with stored vectors using a relatively inexpensive measure such as cosine similarity. The trade-off is that each text is represented by a compressed vector, which may not preserve every detail needed to judge its relevance to a particular query.
A common reranking approach uses a cross-encoder. It processes the query and one candidate document together, allowing the model to assess how the two texts relate and produce a relevance score for that pair. Because that score depends on the query, it cannot be precomputed for every possible query. The model must run on the candidate pairs at search time, which can improve query-specific scoring but adds computation and latency. Cross-encoders are common, but reranking is a broader category: systems may also use multi-vector models, large language models, or heuristic scoring methods.
First-stage retrieval and reranking compared
A simplified comparison of two common stages. Actual systems can use different models and architectures.
| Feature | Bi-encoder retrieval (first stage) | Cross-encoder reranking (second stage) |
|---|---|---|
| Input processing | Encodes the query and documents separately | Processes a query–document pair together |
| Precomputation | Document embeddings can be computed in advance | Pair scores depend on the query and are computed at query time |
| Typical role | Find a candidate set efficiently | Rescore and reorder the candidates |
| Trade-off | Fast comparisons, but compressed representations may lose detail | More query-specific interaction, with additional inference cost |
Examples across different applications
In enterprise documentation search, a query may contain a term used in more than one field. For example, a search for “feature scaling” in machine learning could retrieve a result about resizing features in image-editing software. A reranker that considers the query and candidate text together may judge that the image-editing result is off-topic and place documentation about normalizing numerical variables higher. This illustrates a possible benefit, not a guaranteed outcome for every query or model.
In web search, an initial retrieval stage can gather candidates from sources such as semantic search and keyword-based systems. A reranker can score those candidates against the query and produce a single ordered list. That may help surface results that better match the user’s intent, but the final quality depends on the initial candidates, scoring model, and ranking objective. In code retrieval, the same pattern can be applied to candidate files or snippets: a first stage finds possible matches, then a reranker scores them against a request for a particular function or behavior. It may prioritize code that implements the requested logic over snippets that merely share generic terms. These are application patterns, not evidence that reranking always improves outcomes in those domains.
Common misconceptions and related concepts
Reranking is not the same thing as cosine similarity. Cosine similarity is one possible metric for comparing vectors in an initial retrieval stage. Reranking describes a later scoring and ordering step. A cross-encoder reranker typically makes a relevance judgment by processing the query with each candidate document, rather than comparing two precomputed vectors. Other rerankers may use different mechanisms, so it is not accurate to define every reranking system as a cross-encoder.
Retrieving more documents does not automatically make a generated answer better. A larger candidate set can improve the chance of including useful material, but passing every candidate to a language model may add irrelevant context and consume more of its context window. Reranking can help choose a smaller, better-ordered subset. However, it cannot guarantee answer quality: the first-stage retriever may miss key evidence, the reranker may misjudge relevance, and the selected documents may not contain enough information to answer the query.
Reranking is also not necessarily neural. A learned model such as a cross-encoder is one option; rules, business signals, or combinations of scores can also reorder results. When evaluating a system, it is useful to distinguish these approaches rather than assuming that any second-stage ordering is a neural reranker.
Operational limits: latency and scaling
The main operational trade-off is additional work at query time. A cross-encoder generally scores candidate pairs, so increasing the candidate count can increase inference demand. The actual latency depends on factors such as the model, document and query lengths, hardware, batching, concurrency, and whether inference runs locally or through a hosted service. There is no universal latency-per-pair figure that applies to all deployments.
Reranking is therefore usually applied to a limited candidate set rather than an entire collection. A system might retrieve dozens of candidates and then retain a smaller number for generation, but the right values depend on the application and need to be measured. Hosted reranking services can also add usage-based costs, while self-hosted models require compute and operational capacity. Measure end-to-end latency and retrieval quality on representative queries; increasing the candidate limit or adding a reranker should be treated as a trade-off to test, not an automatic improvement.
Reranking may fail to help—or can make results worse—when the initial retrieval already returns strong results, when the relevant document is absent from its candidates, or when the reranker’s training and scoring behavior do not match the domain or relevance criteria. A model can also rank a plausible but incomplete passage above the passage needed to answer a specific question. Evaluation should therefore compare the full pipeline with and without reranking, using domain-relevant queries and an explicit quality measure.
A practical decision process
Use measurements from your own system to decide whether and how to add a reranking stage.
- 01Measure the quality of the current first-stage results, including the documents that reach the final context.
- 02If relevant material is often present but poorly ordered, test a reranker on a representative query set.
- 03Set a candidate limit for reranking; choose it based on quality and latency measurements rather than a universal default.
- 04Choose how many reranked results to pass to the next stage, taking context limits and answer quality into account.
- 05Compare end-to-end latency, cost, and retrieval or answer quality with and without reranking. Adjust the candidate and output limits if the trade-off does not meet your requirements.
Related concepts and further context
Reranking is commonly used in a two-stage retrieval architecture: an initial retriever finds candidates, and a second-stage model or scoring function reorders them. In a RAG pipeline, that second stage can help select evidence before the language model generates a response. It is related to semantic search, embeddings, and vector databases, but it is not synonymous with any of them: those technologies may power the first stage, while reranking is a separate operation over its candidates.
The examples in technical documentation from Qdrant, NVIDIA, and Pinecone illustrate particular implementations and demonstrations. They explain query–document scoring and the practical trade-off between retrieval breadth and reranking cost, but they do not establish a universal accuracy gain or typical latency for every deployment. Treat any performance claim as specific to the model, data, hardware, and test setup unless broader evidence supports a wider conclusion.
Key takeaways
Reranking is a second-stage operation that rescores and reorders an initial set of retrieved candidates. Cross-encoders are a common approach because they process a query and candidate together, while bi-encoders are often used for efficient first-stage retrieval with separately computed embeddings.
Reranking can help focus the documents supplied to a RAG system or improve the ordering of search results, but its impact depends on candidate quality and the task. It cannot retrieve documents missing from the initial candidate set, and adding more candidates or a reranker is not guaranteed to improve an answer.
Because reranking adds work at query time, teams should measure its effect on latency, cost, and relevance with representative queries. The appropriate candidate count and final output size depend on the system; no single latency or configuration applies universally.