One-sentence definition
Familia de métodos que usa preferencias humanas para entrenar señales de recompensa y orientar el comportamiento de un modelo.
What is RLHF?
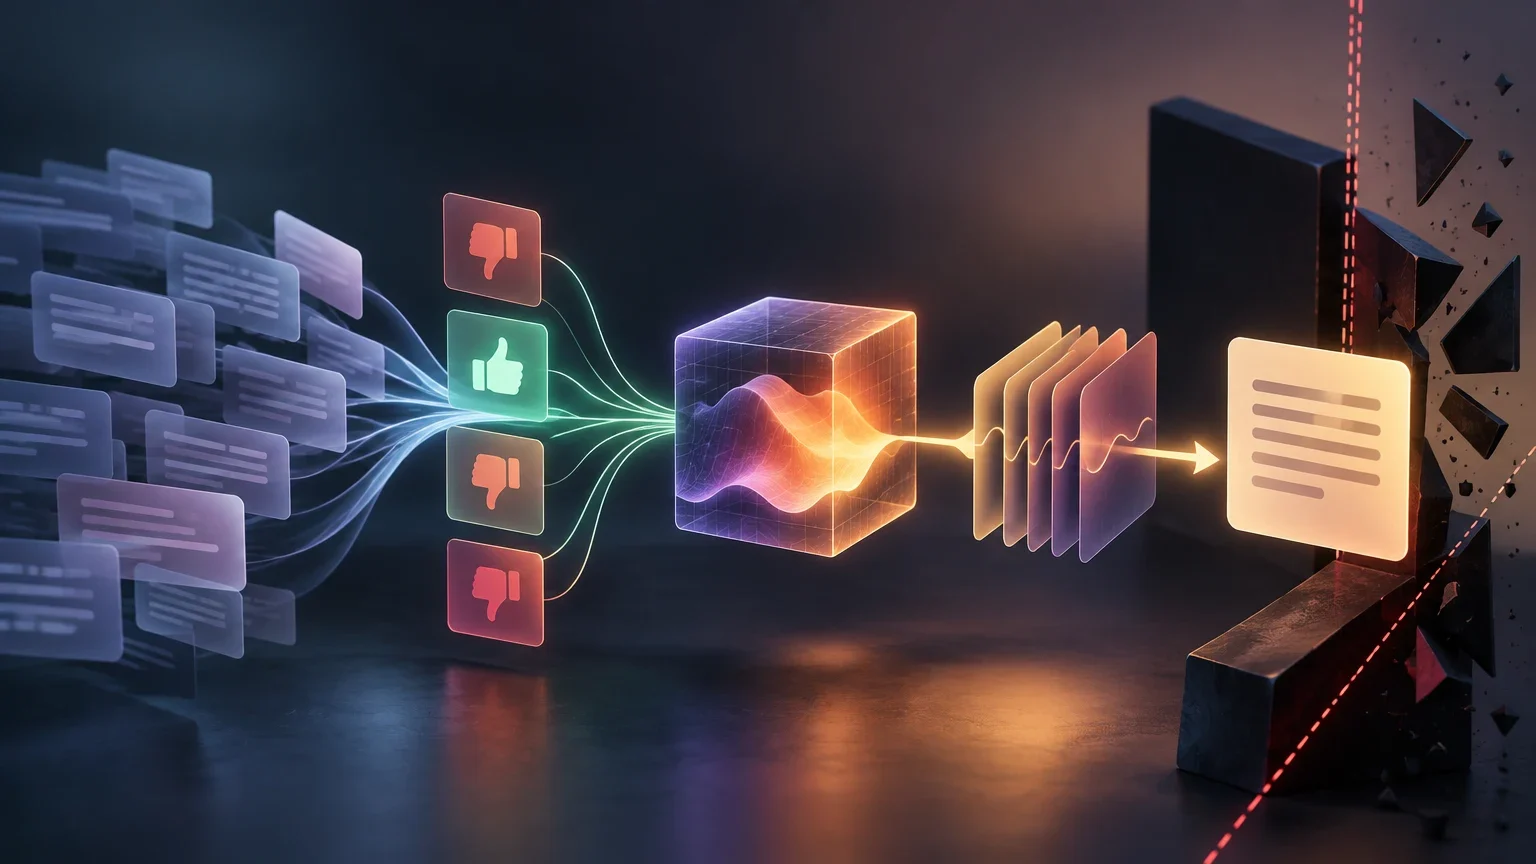
Reinforcement learning from human feedback (RLHF) is a family of methods that uses human evaluations or preferences to construct a reward signal and guide the optimization of a model. In a common implementation, people compare several possible responses; those comparisons are used to train a reward model, which then scores responses generated by the policy being tuned.
The approach is useful when it is easier to judge which of two results is preferable than to write a complete mathematical rule specifying the ideal result. For example, a person may assess whether a response is clear, relevant, or cautious. The reward model approximates those judgments from the available data; it does not turn subjective criteria into a universal definition of quality.
RLHF does not refer to one fixed recipe. The type of feedback, how it is collected, the model used to learn preferences, and the subsequent optimization method can all vary. In language models, a well-known setup combines supervised fine-tuning, human comparisons, reward-model training, and reinforcement-learning optimization. PPO is one possible algorithm for that last stage, not a requirement for every method based on human preferences.
The definition also requires separating the human signal from the procedure that processes it. An observed preference is data, the reward model is a learned approximation, and the optimized policy is the system being changed. Conflating them leads to overstating what the method demonstrates: improving a learned score does not by itself prove that a model is truthful, safe, or representative of everyone’s preferences.
The technical workflow, from data to policy
In a common workflow for language models, the process starts with an initial policy that can produce responses. This policy may come from a pretrained model and may first undergo supervised fine-tuning, where it learns to imitate demonstration responses. Demonstrations and preferences serve different purposes: demonstrations show examples of behavior, while preferences allow candidates to be compared.
Next, the system generates several responses to the same instruction. Human annotators compare or rank them using criteria defined for the project. A pairwise comparison might indicate that, for a particular question, response A is preferred to response B. That judgment records a contextual choice, not necessarily the full reason behind it or agreement among all evaluators.
The comparisons are used to train a reward model. In the common case of pairwise preferences, the model learns to assign scores so that the chosen response tends to score higher than the rejected one. The policy then generates new responses and is optimized to obtain high scores according to that learned reward. Algorithms such as PPO can update the policy; some setups also constrain how far it moves from a reference model.
Each stage produces different artifacts: demonstrations for supervised fine-tuning, annotated pairs or rankings, a reward model, and a tuned policy. Keeping these distinct makes it easier to audit what signal entered the system and how it was transformed. If a stage is omitted—for example, if the model is tuned directly on demonstrations—the procedure should not automatically be described as the classic RLHF workflow with an explicit reward model.
This outline is a reference, not a universal specification. Some designs use other forms of feedback or different optimization methods. There are also preference-optimization approaches that avoid training a separate reward model and then applying a conventional reinforcement-learning loop. It is therefore better to name the specific method than to assume that all preference-based alignment follows exactly the same steps.
Common stages and their outputs
The sequence below summarizes a common language-model setup; details vary across implementations.
- 01Prepare an initial policy; if appropriate, tune it using supervised demonstrations.
- 02Generate several responses for selected instructions.
- 03Collect comparisons, rankings, or other human evaluations using defined criteria.
- 04Train a reward model to approximate the observed preferences.
- 05Optimize the policy using that reward, applying a reinforcement-learning algorithm if the design calls for one.
- 06Evaluate the resulting model separately: the training reward is not a substitute for independent evaluation.
Applied examples
For a conversational assistant, evaluators could be shown two responses to the same question. They might prefer the one that answers directly, distinguishes facts from uncertainty, and avoids irrelevant content. The comparisons can be used to learn a reward aimed at those criteria and then tune the policy. This example illustrates the mechanism; it does not claim that any specific assistant was trained this way.
In content moderation, evaluators might compare the system’s decisions about the same passage: allow it, remove it, or send it for review. The feedback may reflect rules and priorities defined for a particular context. Before using it to optimize a policy, the design would need to specify which harm it aims to reduce, the costs of false positives and false negatives, and how appeals work. A group of annotators’ preferences do not, by themselves, constitute a universal social standard.
In recommendation, a person might prefer one result over another in a particular situation—for example, an option relevant to a specific search rather than a popular option that does not fit the query as well. That comparison could feed a reward model for ranking results. However, a click or observed choice does not always express satisfaction: it may depend on position, interface design, or incomplete information. Before treating such behavior as feedback, it is necessary to clarify the objective being approximated.
The core idea is the same in all three cases—using judgments to build an optimization signal—but the item being evaluated, the people making the judgments, and the consequences of errors differ. Describing an application therefore requires distinguishing a conceptual example from what is documented about an actual system.
RLHF and related concepts
Direct supervised fine-tuning trains a model on demonstrations: an input and a reference response are provided, and the model learns to produce a similar response. This does not necessarily require learning a reward from comparisons or subsequently optimizing the policy through reinforcement learning. It can be part of an RLHF workflow as an initial stage, but it is not synonymous with the entire procedure.
Reinforcement learning without human feedback uses a reward defined in another way, such as an automatic score or a verifiable condition. It is still reinforcement learning, but it does not become RLHF merely because the system optimizes a reward. Conversely, the fact that a person contributed an annotation does not establish that a reward model was trained or that reinforcement learning was applied.
In-context learning occurs when a model uses instructions and examples provided in the prompt to produce an output, without necessarily updating its parameters through the training process described here. It can affect the behavior observed in a conversation, but it is not, by itself, RLHF.
These methods are not always mutually exclusive. A system may use supervised demonstrations before collecting preferences and may combine several forms of evaluation during development. Direct preference optimization methods such as DPO use preference data without necessarily following the explicit cycle of training a separate reward model and optimizing it with a reinforcement-learning algorithm. The most accurate label depends on the components actually used.
A guide to distinguishing methods
The presence of human feedback is not enough to identify every stage of training.
| Method | Main signal | What it does not imply by itself |
|---|---|---|
| Common RLHF setup | Human preferences used to learn a reward and guide the policy | It does not guarantee truthfulness, safety, or universal agreement |
| Direct supervised fine-tuning | Demonstrations of desired inputs and outputs | It does not require a reward model or reinforcement-learning optimization |
| Reinforcement learning without human feedback | An automatic, programmed, or verifiable reward | It is not RLHF if the signal does not come from human feedback |
| In-context learning | Instructions and examples supplied in the prompt | It does not imply that the model’s parameters are updated |
| Direct preference optimization | Preference pairs or rankings used directly during tuning | It does not necessarily require an explicit reward-model-plus-RL cycle |
What preferences can—and cannot—tell us
A human comparison records a choice under specific conditions: who evaluated the options, which alternatives they saw, what instructions they received, and when the judgment was made. It can help train a system to imitate preference patterns in that dataset, but it does not prove that the choice represents the entire population or reflects stable values in other contexts.
A reward model is a learned substitute for the judgments it received. It may generalize poorly to instructions or responses outside its coverage, mistake a superficial signal for the intended quality, or score inconsistently. If the policy is optimized aggressively against that signal, it may find outputs that score highly without fulfilling the underlying human objective. This risk is often called reward hacking or reward overoptimization.
Process decisions matter too: how the criteria are written, which alternatives are generated, which annotator groups participate, how disagreements are resolved, and what distribution of instructions is used. A lack of diversity can leave some preferences or situations underrepresented. More optimization does not automatically fix this; signal quality and evaluation coverage remain important.
For these reasons, RLHF does not by itself certify safety or truthfulness. A model may seem more useful to evaluators and still make factual errors. Desired properties require specific tests, evaluation outside the training data, failure analysis, and—where use is high-risk—appropriate operational safeguards and oversight. The reward should be understood as a training objective, not a certificate of behavior.
Common mistakes and practical checks
One common mistake is to say that “humans directly teach the model human values.” In a typical workflow, people provide bounded judgments, and a reward model learns to predict them. The policy is then tuned against that approximation. The outcome depends on how the criteria were defined, who annotated the data, and how the components were trained and evaluated.
Another mistake is treating demonstrations, comparisons, and ratings as equivalent. A demonstration provides an example output; a comparison indicates which of several options is preferred; a rating assigns a score using a scale. These are different signals and call for different interpretations and training procedures. Likewise, not every post-training adjustment should be called RLHF if the use of human preferences and the mechanism involved have not been verified.
It is also worth avoiding claims that the method “aligns a model with human values” without specifying whose judgments were used and how the result was measured. A more precise description identifies the task, the evaluator population, the type of feedback, and the scope of the evaluation. If an example is merely illustrative, it should be presented as a hypothetical scenario, not as an observed result.
When reviewing a claim about RLHF, ask: What was evaluated? Who evaluated it? What signal was produced? Was a separate reward model trained? What algorithm changed the policy? What independent evaluation supports the conclusion? These questions help distinguish a specific technical description from a broad claim about alignment.
This entry focuses on machine-learning models and, in particular, on the common workflow used with language models. Nathan Lambert’s technical book offers a wide-ranging account of RLHF methods and stages, but the consulted page presents the book as an arXiv version; that evidence alone does not establish that it is peer-reviewed. AWS’s explanatory documentation provides a complementary description of the workflow, but it does not replace the primary papers for individual implementations.
Checklist for describing a system
Use these questions to avoid confusing a training stage, a data signal, and a performance guarantee.
| Question | What to clarify |
|---|---|
| What feedback was collected? | Comparisons, rankings, ratings, corrections, or demonstrations |
| Who evaluated it? | Population, expertise, instructions, and how disagreements were handled |
| How was it used? | Supervised fine-tuning, reward-model training, direct optimization, or another approach |
| What claim is being made? | Observed preference, quality, safety, truthfulness, or another outcome |
| What evidence supports it? | A specific evaluation, separate from training and appropriate to the context |