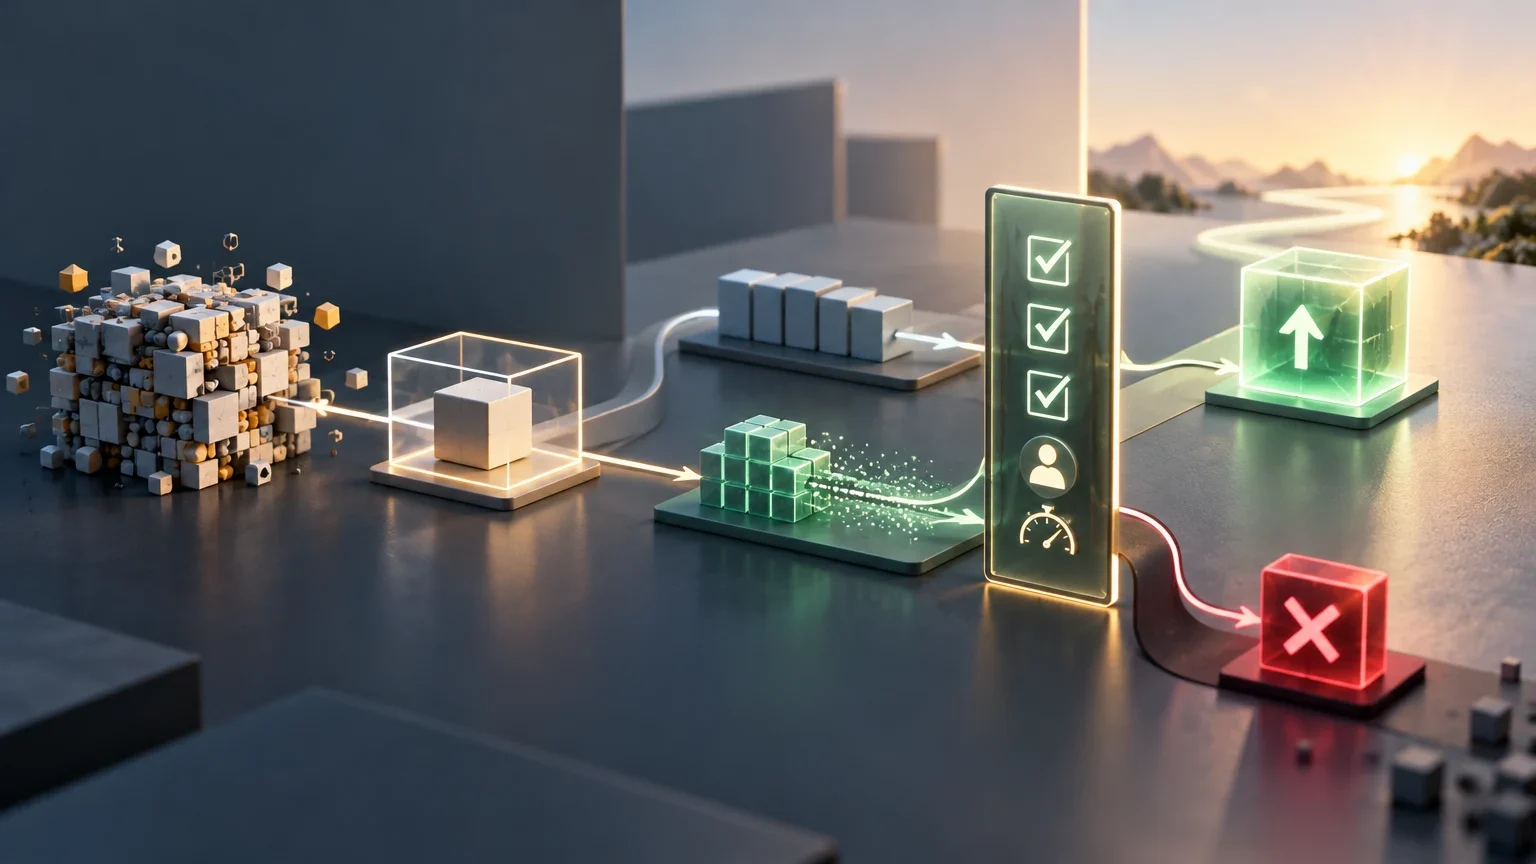
Start with an observable task
A useful pilot is not a demonstration that a tool can produce a convincing answer. It is a way to find out whether a specific intervention improves a task under defined conditions and with a manageable level of review. The question is not “Can AI do this?” but “Does it handle this work better than the alternatives, for these cases and within these limits?”
Describe the work before naming a solution. Identify who performs it, what event triggers it, what information they receive, what result they must produce, how often the task occurs, and what could happen if something goes wrong. Replace vague goals such as “improve productivity” with a verifiable task—for example, extracting specified fields from requests and preparing a classification for a person to review.
Before using a model, consider whether deterministic rules are enough. If the task follows stable conditions—for example, copying complete form fields into a table—a rule may be simpler to evaluate and maintain. AI may be useful when the work involves interpreting variable text, summarizing, classifying, or drafting, but that does not by itself prove it will perform better. Compare the options where relevant. This guide offers a decision method, not a universal standard or a guarantee of savings.
Design a representative test that is hard to bias
Define the unit of testing: a complete request, a document, or a finished task. The unit should match the result that matters in the real work; scoring isolated sentences can hide omissions or errors that only appear in the complete output. Gather ordinary cases as well as examples with missing information, ambiguity, unusual formats, and inputs that should fall outside the intended scope.
Do not assume that a large sample is representative. Describe the kinds of cases you expect to encounter and include relevant variations, such as channel, language, difficulty, input type, and the consequences of an error. If a type of error is rare but serious, include it as a critical test even if it does not reflect everyday frequency. Report those results separately so an average cannot conceal them.
Separate the examples you will use to adjust instructions or rules from the cases reserved to evaluate the final version. If you change the system after seeing the same cases you later present as test results, the outcome may reflect that familiarity. Define in advance what evidence supports each rubric label, and allow a “not evaluable” result when there is not enough context to establish a correct answer.
Prepare the test set
- 01Define an evaluation unit that represents a complete task.
- 02Group ordinary cases, edge cases, ambiguous inputs, exceptions, and critical errors.
- 03For each case, record the expected result and why it is included.
- 04Separate tuning examples from cases reserved for the decision.
- 05Check for duplicates and document any case that cannot be evaluated with the information available.
Compare alternatives under the same conditions
Where possible, the most useful comparison includes the current process and, when reasonable, both a deterministic alternative and AI assistance. Not every task needs all three; if no relevant deterministic option exists, explain why. The current process provides a reference point, but do not treat it as a known baseline until you have measured its quality, time, corrections, and exceptions.
Keep the cases, evaluation criteria, and working conditions consistent. When comparing two configurations, use the same inputs and record any differences in instructions, tools, permissions, or output format. Changing the task to favor one alternative makes it difficult to tell what caused the difference. Track versions and changes so you can repeat the test.
Measure the entire process, including human review. A fast output that must be reconstructed or corrected in every case may not reduce the work. Track how long review takes, what the reviewer changes, when they reject a suggestion, and which cases need to be handed off. Distinguish observed data from interpretation: counting accepted outputs is not enough to conclude that an intervention is ready to expand.
Alternatives to consider
| Alternative | When to include it | What to record |
|---|---|---|
| Current process | Whenever the existing workflow can be observed under comparable conditions. | Quality, total time, corrections, exceptions, and who is involved. |
| Deterministic automation | When explicit rules can handle part of the task without interpreting variable inputs. | Rules applied, cases covered, exceptions, and failures. |
| AI assistance | When the work involves interpretation, classification, summarization, or drafts that can be checked. | Quality by case, errors, abstentions, human review, time, and cost. |
| Combination of rules and assistance | When some steps are predictable and others require interpreting information. | Which component handles each step and how exceptions are managed. |
Turn the goal into criteria and thresholds in advance
Write a simple rubric that lets you classify each case as correct, partially correct, incorrect, or not evaluable. Define which errors are critical and which are minor differences. A stylistic variation may have little impact; routing a request to the wrong team, omitting a required detail, or taking an unauthorized action may block approval even if the overall average looks favorable.
Choose a primary measure that answers the pilot’s main question, then add secondary indicators to explain the result. Possible measures include the share of acceptable tasks, critical errors, correct handoffs, total time, human corrections, and cost per accepted case. Do not treat one metric as a substitute for another: speed, quality, and risk are distinct dimensions.
Before running the test, set the acceptance threshold, stop conditions, and what results would lead you to expand, limit, redesign, or reject the intervention. Thresholds depend on the task’s impact and the organization’s tolerance for errors; the sources available do not establish universal values. If reviewers disagree, resolve that disagreement using explicit rules and record it rather than turning an uncertain assessment into a confident label.
Pre-test decision template
| Element | Definition before testing |
|---|---|
| Primary goal | What specific result should improve. |
| Success criterion | What evidence makes a task acceptable. |
| Critical error | What type of failure blocks approval, regardless of the average. |
| Human review | Who reviews, what they see, and what they can correct or stop. |
| Acceptance threshold | The minimum conditions that must be met for the intended decision. |
| Stop rule | What incident, error pattern, or cost requires stopping or limiting the test. |
| Scope of the conclusion | Users, data, volume, and environment covered by the test cases. |
Run a bounded, reversible pilot
Where the objective allows it, start without affecting live operations—for example, by using historical or synthetic cases or running the system in parallel. If you later need to test with users, show suggestions for review before allowing external actions. Increase autonomy only if the tested scope and pre-agreed criteria justify it. Keep a straightforward way to stop the test and return to the previous process.
For each run, record the version of the instructions or rules, the tools available, the test set, failures, and the human decision. Keep only the information needed to assess the result, and handle data with appropriate permissions. If an input is incomplete or out of scope, define whether the system should abstain and request review; do not force an answer as if the case were ordinary.
The pilot should account for operational effort as well as task outcomes. Include the time needed to prepare, review, and correct outputs; technical costs where measurable; exceptions; and incidents. An author’s published first-person account of testing AI on real tasks describes using pre-set criteria, comparable inputs, measurements, and human approval. It is an individual testimonial that illustrates a practice; it does not demonstrate that the method produces generalizable results.
Execution sequence
- 01Freeze the scope, rubric, metrics, and stop rules.
- 02Run the alternatives on the same cases under documented conditions.
- 03Review outputs using the agreed criteria and record corrections and disagreements.
- 04Group results by case type and severity, not only in an overall average.
- 05Stop or limit the test if a pre-defined critical condition occurs.
- 06Keep the configuration and results summary needed to repeat the evaluation.
Decide what to do—and limit the conclusion to what was tested
At the end of the pilot, choose whether to expand gradually, adjust and repeat, automate only a stable subset, keep human assistance, or abandon the intervention. Explain which results support the decision, which cases failed, what review work remains, and what limitations are still open. A test that does not justify expansion can still be valuable if it prevents a larger decision from being made without enough evidence.
If you expand, specify what changes: higher volume, new categories, different users, or greater ability to take actions. Treat each relevant change as a new condition that may need to be tested again. Do not extrapolate results from a small test set to other languages, environments, data, or risk levels that were not included.
The final summary should separate observations from interpretation. “Some outputs were accepted and others were handed off in this sample” is a bounded result; “the solution will work in production” is a broader conclusion that requires additional evidence. Also record when the system should be reviewed again and who can stop or reverse the change if problems appear.
Options at the end of the pilot
| Observed result | Possible decision | Next step |
|---|---|---|
| Defined criteria are met and no critical failure appears. | Expand gradually. | Test the next volume or segment and repeat the relevant evaluation. |
| There is a plausible improvement, but correctable failures remain. | Adjust and retest. | Change one identifiable part and reassess affected cases. |
| The value is limited to clear, stable cases. | Limit the scope. | Automate only that subset and hand off the rest. |
| Review effort absorbs the improvement, or risk exceeds the observed value. | Keep human assistance or reject the intervention. | Keep the lessons learned and do not expand. |
| A pre-defined stop condition occurs. | Stop the test. | Return to a safe process, investigate the failure, and document the decision. |
Hypothetical example: classifying support requests
This example is illustrative and does not attribute results to a real product or company. Imagine a team receiving requests through a form and wanting to reduce the time needed to prepare and route them. The scope is limited to messages in one language, five categories, and a proposed classification that a person approves. Sensitive requests, new categories, and messages without enough information are excluded.
The test set includes ordinary requests, ambiguous messages, missing fields, out-of-scope cases, and errors that could lead to incorrect routing. The comparison includes the current manual process, a deterministic rule for explicit cases, and AI assistance for interpreting variable text. All three alternatives use the same rubric; the team records review time, corrections, handoffs, and errors by category.
Before running the test, the team defines what counts as an acceptable classification, which errors are critical, and what condition requires a stop. No fictional percentages are set: the threshold would depend on actual frequency, the consequences of an error, and the organization’s tolerance. If AI helps only with clear messages, a reasonable decision might be to limit it to that subset and hand off ambiguous cases. If the required review removes any benefit, the team can keep the current process or redesign the task.
Checklist before approving the pilot
Before approving a pilot proposal, check that the task and its exclusions are defined, the test unit reflects the complete work, and the cases cover relevant variation. Also confirm that the comparison with the current process is fair and that a deterministic solution is included when it makes sense.
Make sure the rubric, critical errors, thresholds, and stop conditions were set before results were observed. Review the full human and operational effort, not just the generated output. If expansion is proposed, ask the recommendation to identify which new conditions would be added and what further evidence would be needed.
The material available for this guide consists mainly of commercial guides and a personal testimonial. These offer practical guidance, not independent proof that a single protocol guarantees better results. Decisions, thresholds, and scope must therefore be justified for the specific task, without presenting general recommendations as demonstrated outcomes.
Quick approval checklist
- 01Are the task, its owner, inputs, output, and exclusions described?
- 02Are there ordinary, ambiguous, incomplete, out-of-scope, and critical cases?
- 03Have tuning cases been separated from cases reserved for evaluation?
- 04Were relevant alternatives compared under documented conditions?
- 05Were the metrics, rubric, thresholds, and stop conditions set before the test?
- 06Are human review, time, and costs included in the evaluation?
- 07Is the conclusion limited to the users, data, volume, and environment tested?
Open questions
- The available sources do not establish universal sample sizes, acceptance percentages, or thresholds; these must be set according to the task, the severity of errors, and risk tolerance.
- The published account of one author’s AI tests is testimonial and does not demonstrate generalizable results or independent replication.
- The available commercial guides provide secondary guidance, not independent primary evidence that a specific protocol guarantees improvements.
- A sample’s representativeness depends on the actual variation in the process; without data about the specific task, it is not possible to determine which strata or volumes will be sufficient.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction