One-sentence definition
Técnica de ajuste eficiente que entrena pequeñas matrices adicionales en lugar de modificar todos los parámetros del modelo.
What Is LoRA?
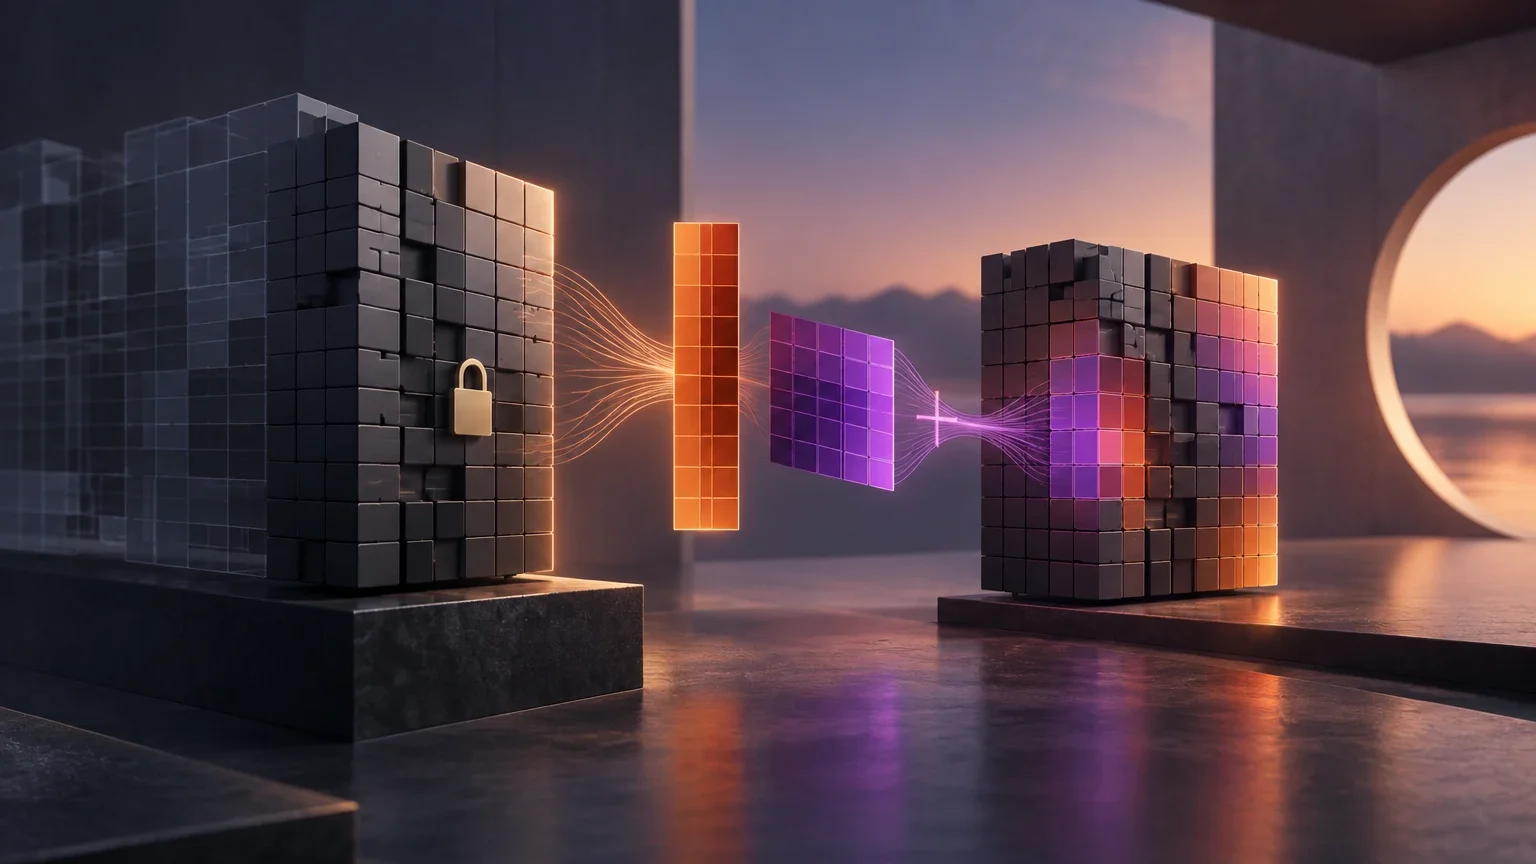
LoRA, short for Low-Rank Adaptation, is a technique for adapting a pretrained model to a task or context without updating all of its original weights. Instead of directly modifying the model’s full set of parameters, it keeps those weights frozen and adds trainable low-rank matrices. During adaptation, training adjusts the added matrices.
The central idea is to separate what the model learned during pretraining from the changes needed for a particular task. The starting model retains its original parameters; the adaptation is represented by smaller additional components. The original paper presents LoRA as a method that freezes pretrained weights and introduces trainable low-rank decomposition matrices.
LoRA is used when someone wants to adapt a model and aims to train fewer parameters than would be required by updating all the weights. That describes the method’s design; it does not, by itself, prove that LoRA will be cheaper in every system, produce better responses, or suit every task.
How It Works: Fixed Weights and Trainable Matrices
To understand the mechanism, imagine a model transformation represented by a pretrained weight matrix, which we will call W₀. In conventional fine-tuning of all weights, training can modify W₀. In the conceptual description of LoRA, W₀ remains frozen and the adaptation is expressed as an additional update, ΔW, approximated by the product of two smaller matrices: ΔW = B × A.
In simplified notation, if W₀ transforms vectors of dimension d_input into vectors of dimension d_output, A can have dimensions r × d_input and B can have dimensions d_output × r. The value r represents the rank used in this representation and is usually smaller than the full dimensions of the transformation. The resulting operation can be described as W₀ + ΔW, although implementations can differ in how they organize, scale, or apply these components.
The intuition is not that the original model stops participating: its weights continue to provide the representation learned previously. What is learned during adaptation is the additional matrices. Therefore, saying that “LoRA trains fewer parameters” refers to the parameters updated during that process, not necessarily to all the resources used by an execution or to the size of the entire system in production.
The mathematical representation above is an explanatory outline of the low-rank matrix approach, not a universal specification for every implementation. To reproduce a particular result, consult the relevant technical configuration: which components receive adapters, what rank is selected, and how the update is integrated with the model.
Conceptual sequence for a LoRA adaptation
- 01Choose a pretrained model and a specific adaptation task.
- 02Keep the pretrained weights frozen in the procedure described by LoRA.
- 03Add trainable low-rank matrices as adaptation components.
- 04Train those matrices on data relevant to the task, without assuming that any dataset will be sufficient or appropriate.
- 05Evaluate the adapted model on representative examples and review its limitations before deciding whether it is suitable for the intended use.
Three Applied Examples
The following cases are illustrative: they describe how an adaptation might be set up, not observed results or a recommendation that LoRA is the right choice. In each case, the decision would depend on the available model, the data, the metrics, and the project’s constraints.
blocks
How It Differs from Related Methods
LoRA is often compared with other ways to customize or adapt models, but the techniques do not necessarily change the same parts or pursue the same goal. These are conceptual distinctions: a specific implementation can combine techniques, so check what was done in each case before comparing results.
blocks
What changes with each approach
The table summarizes general differences. It does not claim that one option is superior or that all implementations behave identically.
| Approach | What is adjusted or changed | Useful question |
|---|---|---|
| LoRA | The pretrained weights remain frozen, and additional low-rank matrices are trained. | Does an adaptation represented by these components work for the task? |
| Full fine-tuning | The model’s own weights are updated during fine-tuning, rather than limiting training to LoRA matrices. | Is it necessary to adapt the full set of weights, and are suitable resources and controls available? |
| Quantization | The model is represented or stored using reduced numerical precision; on its own, this does not define an adaptation task. | Is the goal to reduce representation or execution requirements, and what effect does that have on quality? |
| In-context learning | Instructions or examples are provided in the input to guide a response, without this implying that weights are trained at that point. | Is changing the input context enough to obtain the required behavior? |
What LoRA Does Not Guarantee—and Common Misconceptions
A common mistake is to interpret “fewer trainable parameters” as meaning “lower total cost.” The design reduces the number of parameters updated compared with fine-tuning that modifies all weights, but total cost also depends on the configuration, data, hardware, training, evaluation, and how the model is served. Without measuring these conditions, it is not possible to conclude how much a particular project will save.
Nor does it follow that the model will be more accurate. Quality depends on the task, the starting model, the quality and representativeness of the data, the configuration, and the evaluation method. An adaptation may learn useful patterns, fail to generalize to new cases, or reinforce biases present in the examples. Parameter counts do not replace comparative testing.
LoRA should also not be confused with a completely new model. In the formulation described here, the adaptation is added to the pretrained model, whose weights remain frozen. The usefulness of the adapted component depends on its relationship to that base model and on how it is applied. Simply retaining trained matrices and separating them from the original model is not enough to assume they form a self-sufficient system.
Finally, training fewer parameters does not prove that the process is safe. Safety requires defining risks, preparing data responsibly, evaluating adverse behaviors, and maintaining controls appropriate to the context of use. An adaptation technique describes how one part of adaptation is carried out; it does not replace those tasks.
Practical Criteria for Deciding Whether to Explore LoRA
Start by defining the task. “Customize a model” is too general: specify what behavior should change, what should remain unchanged, who will use the system, and which failures would matter. If the problem can be solved with instructions, in-context examples, or a document collection, parameter adaptation may not be necessary.
Next, check that suitable data are available to teach and evaluate the desired behavior. Simply accumulating examples is not enough: they should represent common and relevant cases, respect the conditions of use, and allow independent evaluation. When a task depends on frequently changing information, adapting the model does not prove that it knows recent facts.
The comparison should include a clear baseline, such as the unadapted model or a relevant alternative, and measure results using the same criteria. Beyond an aggregate metric, it is useful to inspect error types, edge cases, and differences across subgroups or operating conditions. If the goal is to reduce cost or execution requirements, measure actual resource use as well.
Finally, document the specific configuration: base model, data, adaptation parameters, evaluation procedure, and known constraints. LoRA is a technical option to evaluate under these conditions, not a decision that can be made solely from model size or a general claim about efficiency.
Checklist for a responsible evaluation
- 01Define the target behavior and the errors that must be avoided.
- 02Check whether instructions, in-context examples, or another simpler solution would be sufficient.
- 03Verify that the adaptation data are relevant and that the evaluation can detect failures.
- 04Compare LoRA with a baseline using equivalent criteria and conditions.
- 05Measure quality and resources in the intended environment; do not infer them solely from the number of trainable parameters.
- 06Record limitations and review behavior before expanding use.
Related Concepts and Limits of the Available Information
LoRA belongs to the family of parameter-efficient model adaptation methods. The defining feature identified in the primary source consulted is that it freezes pretrained weights and introduces trainable low-rank decomposition matrices. “Fine-tuning” is a broader term for adapting a model through training; it does not necessarily mean LoRA was used. “Quantization” describes a different concern related to the model’s numerical representation, while in-context learning changes the input information, not the weights merely by including examples.
These categories can be combined in real systems. So, to understand a claim about a model, ask which weights were updated, what numerical representation was used, what information was supplied in the input, and what evaluation supports the result. A technique’s name, without those details, is not enough to reconstruct a configuration or attribute performance to it.
The verified information available for this guide supports the essential description of LoRA, but it does not establish recommended configurations, quantitative results, improvements over alternative methods, or universal conclusions about computational limits. Those points require consulting the full technical text and the documentation for a specific implementation. Therefore, the comparisons in this guide are conceptual distinctions, not the results of a comparative test.