What question does this evaluation answer?
A retrieval-augmented generation system, or RAG system, receives retrieved documents and uses them as context to answer questions. The proposed test asks a narrow question: when Command R 08-2024 is given a specified set of document excerpts, can it distinguish what those excerpts support, what they contradict, and what they do not allow it to answer? The test is not intended to measure the model’s full language capability or reproduce a score published by the provider.
The unit of analysis is an answer generated from a specified document context. The evaluation will separately assess answer accuracy, support for the answer’s claims, citation quality, handling of contradictions, and the decision to abstain. Separating these dimensions helps prevent a fluent answer or an aggregate score from obscuring different kinds of failure: for example, a conclusion that happens to be correct, a citation that mentions the topic but does not establish the claim, or an abstention despite explicit information in the documents.
The scope also excludes broad conclusions about every Command R version, Command R+, or the production performance of a complete system. A test using a particular corpus, set of instructions, and configuration describes those specific conditions. On its own, it cannot establish that the model will perform the same way with other documents, users, retrieval configurations, or service conditions.
Identify the model before testing it
A product name alone is not enough to identify reproducibly which system generated an answer. The record should include the exact identifier, access channel, date of each run, and available configuration. It should also preserve the request that was sent and, where the channel allows it, the generation parameters and any returned metadata. If a provider changes the model behind a name without allowing users to pin a revision, that limitation must be recorded as part of the method.
Cohere’s documentation about the August refresh identifies Command R 08-2024 and describes improvements in multilingual retrieval-augmented generation and tool use. That description documents what the provider says about the update, but it is not an independent test of this protocol’s metrics. A model card or provider evaluation therefore cannot stand in for the controlled experiment proposed here.
The Oracle documentation available for this article identifies cohere.command-r-08-2024 in its service and marks the model as deprecated. This is relevant evidence of a limitation in that channel, but it does not show that the identifier is unavailable elsewhere. The Cohere Labs repository, in turn, identifies an open-weight research release. Before running the test, researchers would need to check directly which artifact or service they will use, which specific version it provides, and what terms of use apply. The available sources are not sufficient to confirm current availability or all operational parameters.
Minimum record of identity and configuration
Complete one row per run or batch of runs. If a field cannot be fixed or verified, record it as unknown rather than filling it in by inference.
| Item | What to record | Why it matters |
|---|---|---|
| Model | Name, exact identifier, and revision if available | Prevents results from being attributed to a different or indeterminate version. |
| Access | Service or artifact used and date accessed | Makes the channel clear and helps identify availability limitations. |
| Input | Instruction, question, and supplied excerpts, including their order | Shows the context the model actually received. |
| Generation | Available parameters and the values used | Helps interpret differences between runs. |
| Incidents | Errors, empty responses, limits, or observed changes | Prevents failures from being excluded without disclosure. |
Build a corpus with three conditions
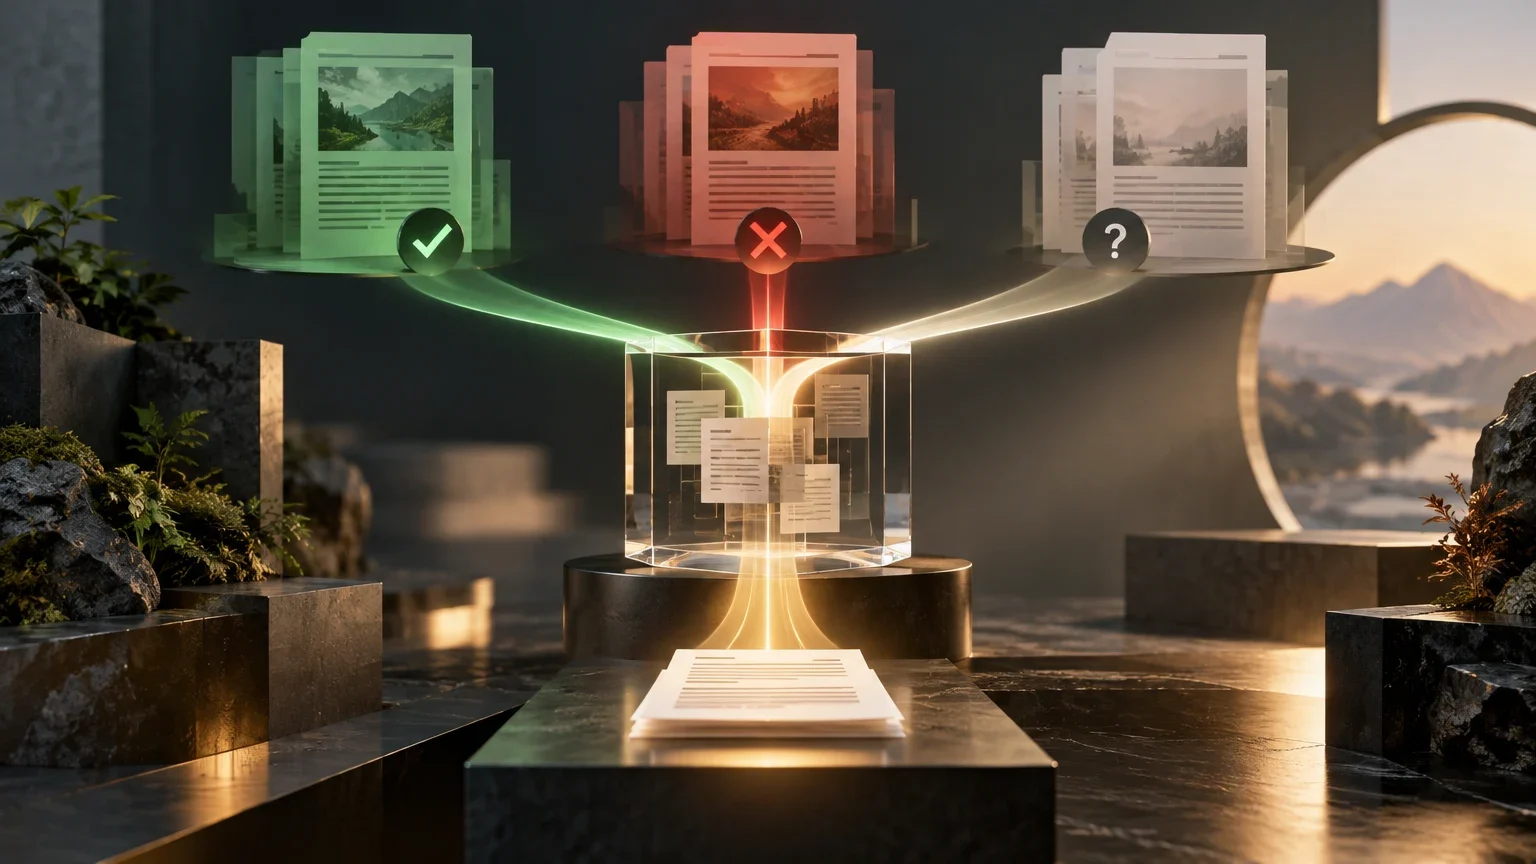
The test set should include three classes of cases, distinguished during study design. In sufficient-evidence cases, an answer can be derived from one or more identifiable passages. In contradictory-evidence cases, two or more documents support incompatible versions of a relevant fact. In cases with insufficient evidence, the supplied material does not justify an answer, even if the question sounds plausible. This third category should not be confused with a document that is merely difficult to find: absence must be verified within the corpus defined for the test.
It is advisable to use controlled documents with recorded provenance and dates, and to write questions before observing the model’s answers. For each question, a reviewer should first determine which passages support it, whether there is a conflict, and what information is missing. This review establishes the reference label and reduces the risk of deciding after the fact that an unexpected answer was correct simply because it sounds reasonable.
The corpus should represent the intended use cases without introducing accidental differences between categories. If contradictory cases are much longer or use different formats than sufficient-evidence cases, results may reflect those differences as well as the ability to recognize conflicts. A composition table should report the number of questions per condition, document count and length, languages, dates, and selection criteria. These design choices should not be presented as a universal sample of internal documentation.
Prepare and review the test set
- 01Define the document domain and record the provenance and date of each item.
- 02Write questions whose answers can be located, whose evidence conflicts, or that cannot be justified from the corpus.
- 03Assign each case a condition and record the relevant passages or why sufficient evidence is unavailable.
- 04Have people review the classification in advance, without showing them the model’s answers.
- 05Resolve or record disagreements before running the test, then freeze a version of the set for the experiment.
Fix retrieval, instructions, and execution
To evaluate how the model handles evidence, every component that affects the context must be described. If the question is supplied together with preselected excerpts, the test measures the model’s answer conditioned on those excerpts—not the quality of a search system. If a retrieval component is used, preserve the query, candidate documents, order, number of excerpts, and selection rule as well. Without this distinction, a retrieval failure could be attributed to the generative model, or vice versa.
The instruction should be the same for every case unless a controlled comparison deliberately changes one variable. It should say how to present evidence and what to do when evidence is missing or contradictory. The wording of the abstention instruction deserves particular care: an ambiguous instruction may measure how the model interprets the prompt as much as its ability to recognize insufficient evidence. The literal prompt should therefore be published and not adjusted case by case after outputs have been seen.
The plan must specify how many runs will be made for each question. If the access channel does not allow certain parameters to be controlled or observed, record that fact. Repeating a run can help reveal variability, but does not automatically make the test set representative. Failed outputs and responses that do not follow the requested format should also be retained rather than silently discarded.
Measure each dimension separately
Factual accuracy assesses whether the answer agrees with what can be established from the corpus and the reviewed reference. Support for claims asks something different: whether each substantive claim in the answer is supported by the supplied documents. An answer may get the main fact right while adding details the corpus does not support; a single “correct” label would hide that problem.
Citation evaluation should check whether the cited passage supports the specific claim attached to it. A topical match is not enough: a citation that mentions a return does not necessarily establish the stated deadline. If the output contains no explicit passage references, mark this dimension as not assessable or adapt it to the agreed format; do not score it as though citations were present.
Contradiction handling should measure whether the answer detects the conflict, identifies the relevant versions, and avoids presenting one as indisputable without support from the documents. Appropriate abstention should distinguish abstaining when support is missing from an unnecessary refusal when the corpus does contain an answer. Rates or counts can be reported for each category, provided they are accompanied by denominators, annotation rules, and examples. Reducing all dimensions to one aggregate score is not recommended unless the weighting is justified.
Proposed annotation rubric
Apply the rubric to each response and preserve the evidence supporting every label. The scales can be adjusted before the test, but not after the results are known.
| Dimension | Annotator’s question | Failure it is intended to detect |
|---|---|---|
| Factual accuracy | Is the answer consistent with the reference based on the corpus? | An incorrect fact or a conclusion unsupported by the available evidence. |
| Support | Is every substantive claim supported by the excerpts? | Additional details with no documentary support. |
| Citation | Does the cited passage support the specific claim? | A topical, incomplete, or irrelevant citation. |
| Contradiction | Does the answer recognize incompatible versions and represent the conflict? | Silently selecting one version or presenting unwarranted certainty. |
| Abstention | Does the model answer when there is support and abstain when there is not? | Inventing an answer when evidence is absent, or refusing unnecessarily when evidence is sufficient. |
Annotation, controls, and contamination
Annotation should follow rules written before reviewers examine the outputs. Where feasible, two reviewers can assess responses independently and without knowing which configuration produced each answer. Disagreements should not disappear into an opaque average: record which dimensions are disputed, how each case is resolved, and which examples remain ambiguous. It is also useful to preserve both the original responses and the normalized versions used for analysis, with an explanation of any transformations.
Contamination of the evaluation set is a different limitation from retrieval quality. Questions or documents that appeared in training data could influence an answer, but the sources available here do not establish whether that happened for any particular set. Describe what is known about document provenance and when the questions were created, and state explicitly what prior exposure cannot be checked. Do not claim that a set is free from contamination without enough evidence to support that claim.
Controls should also check that reference labels do not inadvertently reveal the answer in the question itself, that excerpts are supplied consistently, and that access failures are not mistaken for model responses. If the prompt, retrieval process, or corpus changes partway through the study, treat the new condition as a separate variant and document it. Comparability depends on being able to reconstruct what changed.
Comparability and limits of interpretation
A test of this kind describes observed behavior under a particular configuration, corpus, and set of instructions. It is not enough to conclude that Command R 08-2024 is suitable for every RAG system, nor to rank models evaluated using different documents, prompts, access channels, or rubrics. A direct comparison with Command R+ would require a parallel evaluation using identified versions and equivalent conditions; the protocol described here provides no comparative results.
Provider statements about an update can help identify which capabilities are intended to improve, but they must not be turned into results of this experiment. Similarly, the availability status of one channel does not necessarily describe other channels. If one access route uses open weights and another uses a managed service, the report should treat them as different configurations unless it can verify that they use the same artifact under comparable conditions.
Generalization also depends on the corpus design. A small set or one concentrated in a single document area may be useful for detecting failures and debugging a configuration, but it does not justify promising the same behavior in other domains, languages, or document types. The report should communicate uncertainty and coverage, not just the most striking result. If the exact model cannot be identified and pinned, the methodologically honest choice is not to publish scores attributed to that version.
Publish so others can repeat the test
A reproducible report should include the protocol, identifier and access channel, execution date, literal instructions, recorded configuration, context format, questions, annotation rules, and disaggregated results. It should also explain how invalid outputs, service errors, and reviewer disagreements were handled. If an item cannot be shared, specify what it is and why; do not disguise a missing artifact as a fully reproducible method.
Before publishing documents or queries, check whether rights, confidentiality, or other terms prevent disclosure. If they cannot be shared, possible alternatives include describing the structure of the test set, publishing synthetic examples clearly labeled as such, or providing a controlled evaluation. These options do not automatically replace publishing the data: they reduce the opportunity for independent replication, and that limitation should be explicit.
For a team, the practical conclusion is to use the test as a diagnostic filter, not as automatic authorization to deploy. If the system answers with citations, inspect whether those citations support the claims. If the main risk is outdated or contradictory documents, test those cases with the team’s own materials and appropriate resolution rules. If safe abstention is required, define acceptable behavior for the specific domain before observing the answers.
Checklist before publishing results
- 01Confirm the exact identifier and describe any uncertainty about revision or access channel.
- 02Publish the corpus or explain precisely what restrictions prevent sharing it.
- 03Include prompts, configuration, questions, context format, and annotation rules.
- 04Report every metric separately, with its denominator, limitations, and examples of errors.
- 05Disclose what could not be verified about access, parameters, prior exposure, or reproducibility.
Conclusion: a protocol is not a result
The useful question is not whether a model “cites well” in the abstract, but what it does when given defined evidence under conditions other people can inspect. Separating sufficient evidence, contradiction, and absence makes it possible to design different controls for each situation. Separating accuracy, support, citation quality, and abstention prevents a single score—or a persuasive answer—from hiding relevant errors.
The verified sources available for this article identify Command R 08-2024 in Cohere documentation and a Cohere Labs repository, and indicate that the Oracle documentation consulted marks the model as deprecated in that service. They do not establish that the proposed test was run, confirm current access through every channel, or provide independent results on citations, contradictions, or abstention. This article therefore presents the design and its validity conditions without attributing scores to the model.
A team applying the protocol to internal documentation will need to create its own reviewed test set, define what counts as a supported answer, and decide what levels of uncertainty are acceptable. Only after verifying the version and running the recorded conditions does it make sense to report results. Even then, conclusions will be limited to the configuration and corpus studied.
Open questions
- Current access to the exact Command R 08-2024 identifier has not been verified, nor have the parameters that can be fixed through each access channel.
- The supplied Oracle documentation says the model is deprecated in OCI; this does not establish that it is unavailable through other channels.
- The protocol has not been run, so there are no experimental results to attribute to the model.
- The supplied sources do not establish whether documents or questions in any particular test set appeared in training data.
- Whether the corpus, questions, and configurations can be published depends on rights, confidentiality, and terms of use that must be checked in each case.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction