Laboratory
Entity that develops or publishes the model and maintains its technical and safety documentation.
Explore the documented models, published evaluations and primary sources associated with this organisation.
Flash model for long-running software engineering, autonomous agents, and complex business flows.
16 SEP 2026↗ MULTIMODAL REASONINGMultimodal reasoning, coding, and complex problems.
16 SEP 2026↗ PREVIOUS FLASH · AGENTSPrevious Flash generation for complex code, agents, and multi-stage execution; useful as a comparison point with Gemini 3.8.
18 SEP 2026↗ EFFICIENT NATIVE IMAGE MODELProduction image model that combines generation, editing, and visual reasoning with a balance of quality, cost, and latency.
07 OCT 2026↗ CINEMATIC VIDEO WITH AUDIOCinematic video model with native audio, scene extension, and control through frames and reference images.
18 SEP 2026↗ MUSIC GENERATIONMusic model for full songs with vocals, lyrics, and control over structure, style, duration, and instrumentation.
18 SEP 2026↗ UNIFIED MULTIMODAL EMBEDDINGEmbedding model that places text, images, video, audio, and PDFs in a shared vector space for search and multimodal RAG.
18 SEP 2026↗ BUILT-IN SPATIAL REASONINGModel specialized in physical understanding, video, spatial reasoning, and tool orchestration for robotic systems.
18 SEP 2026↗ MULTIMODAL REASONING AND COMPLEX AGENTSGoogle model generally available since October 13, 2026. It accepts text, images, audio and video and generates text, including code; it does not generate images, audio or video. It uses a MoE architecture and a shared 1,048,576-token window. Robotics applications use this same model, not a separate endpoint.
14 OCT 2026↗ IMAGE GENERATION AND EDITINGGoogle model for image generation and conversational editing, generally available since October 6, 2026. It replaces Nano Banana 2 and should not be confused with Nano Banana Pro. It accepts text, images, video and PDF as context; it produces images and text, not video or audio. Google reports improvements in visuals, instruction following, text rendering and consistency across edits.
07 OCT 2026↗ REAL-TIME MULTIMODAL CONVERSATIONLive conversation model integrating voice, video, and tools with low latency.
29 SEP 2026↗ LIVE VOICE WITH EXTENDED REASONINGLive voice variant with background reasoning for complex multi-step tasks.
29 SEP 2026↗Figures are shown with the context reported by their source. A provider result is not an independent comparison and does not replace your own evaluation.
An organization, a product, and a model are not the same unit. Inferama separates them to avoid attributing capabilities or commercial terms to the wrong item.
Entity that develops or publishes the model and maintains its technical and safety documentation.
Identifiable version with limits, modalities, and behavior that may change between releases.
API, application, associated cloud, or commercial plan; each channel may have different pricing, retention, and limits.
Every claim must retain the official page consulted and the verification date.
Google describes Gemini 3.8 Live Extended Thinking as an audio-to-audio model for the Live API, recommended when more background reasoning is needed. The available documentation does not, by itself, show that this reduces errors or improves latency. Those questions require testing with controlled tasks and conditions.
02 Oct 2026 ↗
Google describes Gemini 3.8 Live as a model for real-time dialogue, but the available sources do not confirm a price, quantitative results, or complete access conditions. This guide separates the provider’s claims from what a team should verify in its own integration.
02 Oct 2026 ↗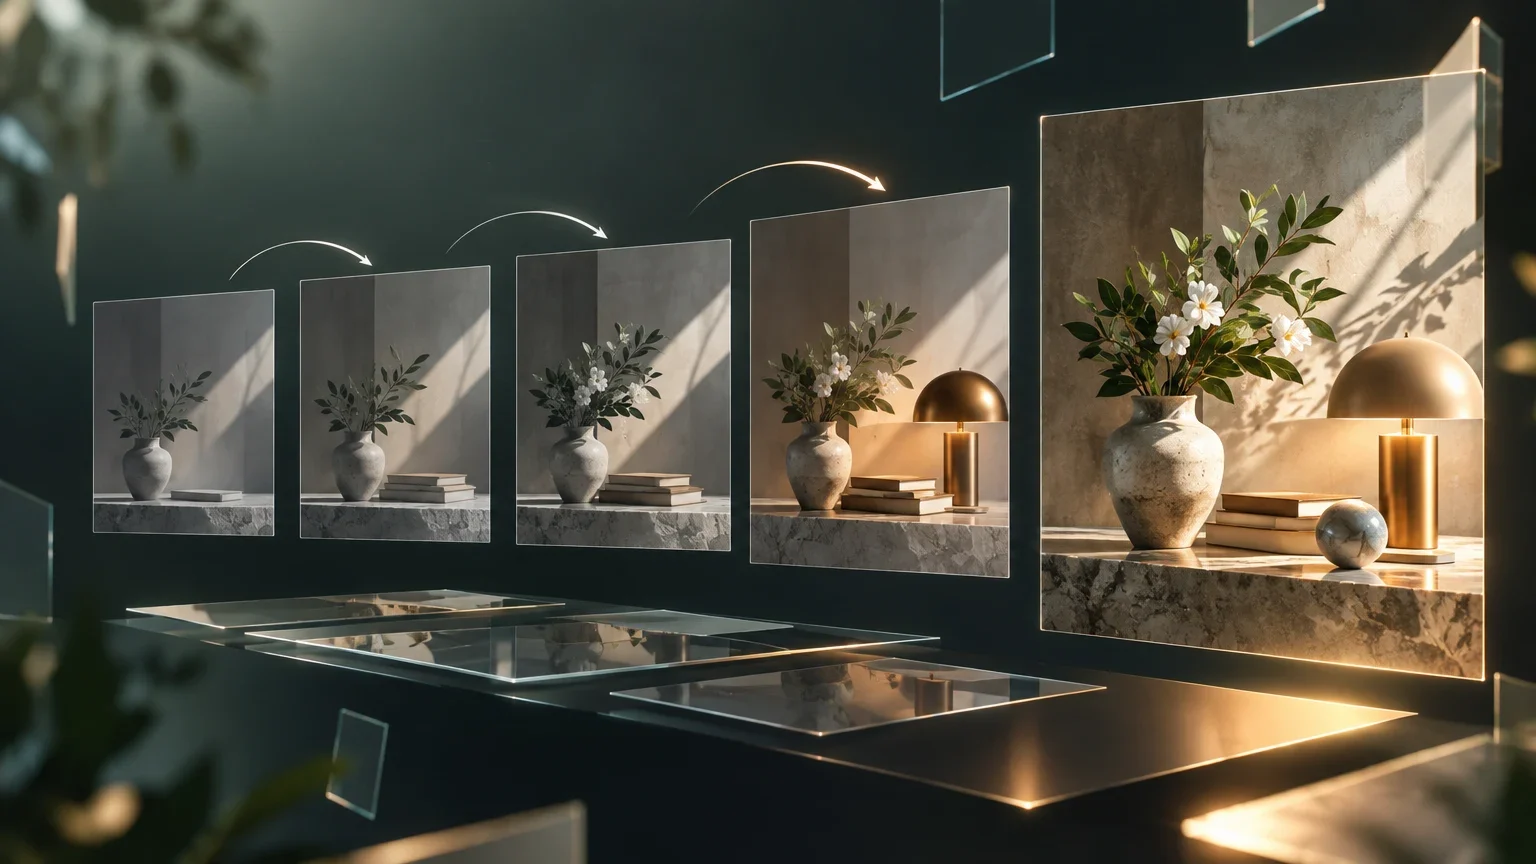
A proposed protocol for measuring whether Nano Banana 2 applies successive changes while preserving the elements that instructions do not ask it to modify. This is not an experimental results report: it sets out what would need to be run and documented to obtain such results.
01 Oct 2026 ↗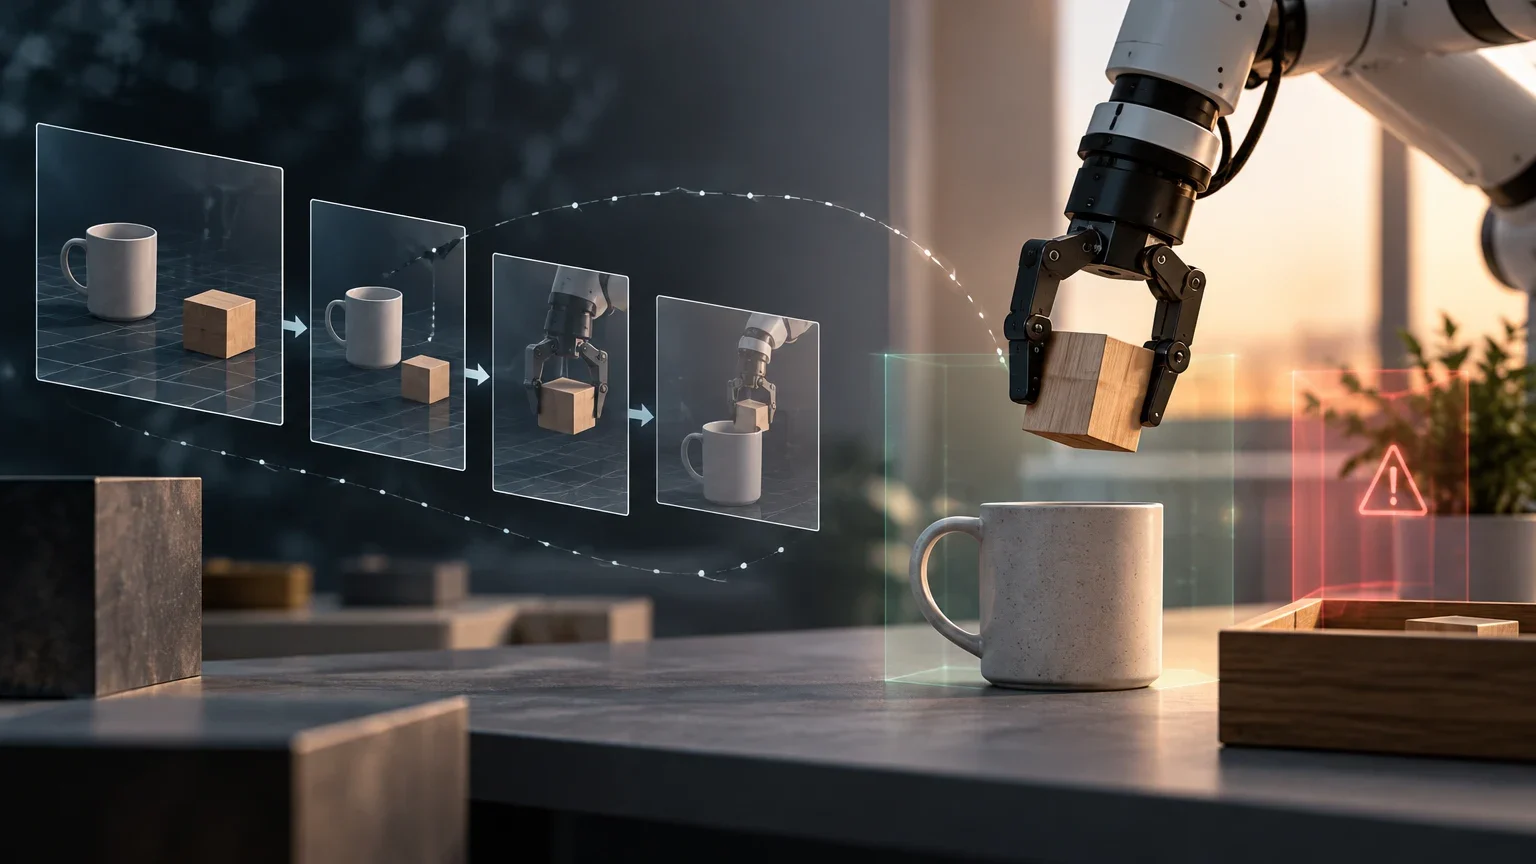
Gemini Robotics ER 2 is presented as a vision-language model capable of planning multi-step tasks for robotics. That does not show that it directly controls a robot or that its plans are safe or reliable in every environment. We examine what the available documentation supports and what each team must test.
30 Sep 2026 ↗
Google’s documentation describes a model that represents text and other types of content in a shared embedding space. That supports a stated capability, not a conclusion that it improves retrieval on any particular corpus. We review what the available sources can establish about performance, access, pricing, and data, and what teams should verify before testing it.
30 Sep 2026 ↗
Google positions Gemini 3.8 Flash for long-horizon software engineering and autonomous agents. That stated focus does not, by itself, show that the model can reliably complete extended tasks. This review separates the provider’s claims from documented access and Agent Platform pricing conditions, and identifies evidence that is missing from the sources reviewed.
30 Sep 2026 ↗