A methodological guide to distinguishing experimental robustness from generalization and reproducibility, reconstructing test conditions, and drawing conclusions proportionate to the evidence observed in AI research.
A methodological audit of the 'Content' metric within the AesCode benchmark. This analysis defines its role in evaluating semantic fidelity of code-generated infographics, its integration with other visual metrics, and the specific limitations that prevent direct comparison with other industry standards.
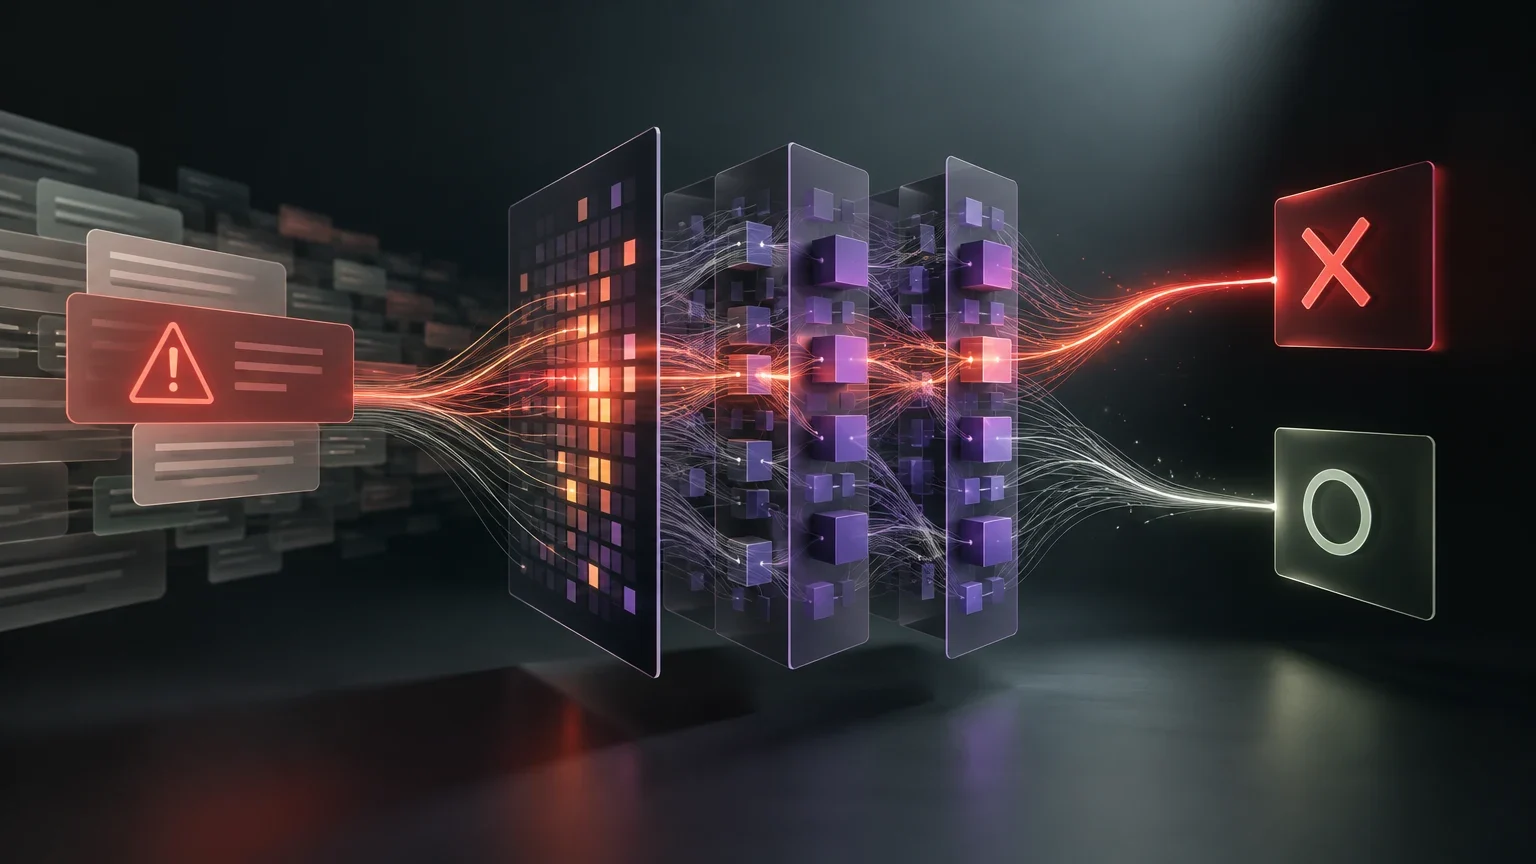
An interpretability study traces how attention and MLP layers contribute to detecting harmful requests and generating refusal signals in language models.
A new preprint presents a 20-task benchmark designed to measure the ability of coding agents to resolve faults in deployed applications, overcoming the limitations of traditional test repositories.
A preprint introduces a method that connects a speech encoder to a frozen LLM to answer closed-set questions via probability distributions over options, reducing latency in real-time voice agents.
Muse Spark Open is attributed with 816 billion parameters, 42 billion active parameters, and a one-million-token context window. However, the available primary documentation from Meta does not confirm this variant or official Apple Silicon optimization; local hardware requirements and performance also remain unverified.
Nemotron 3.5 Super VL is designed to interpret documents, charts, images, and video while supporting long-running tasks with tools. Available information confirms the launch and model scale, but it is insufficient to establish independent performance or the specific NVIDIA hardware required for each deployment.
An experimental paper describes a way to stabilize looped Transformers and measure their performance. It does not show that OpenAI uses this approach in its next model, nor does it establish that the architecture makes safety oversight harder.
A guide to connecting a model with an internal tool without granting it direct authority to modify data: define a scoped interface, validate every proposal in code, and deploy with controls and rollback.
An analysis of the Aleph Alpha–Cohere combination: confirmed facts, potential effects on sovereign model availability, regulatory implications, and a checklist for verifying licences and access channels.
Before investing in AI, define the decision you want to improve, the data you have, and the consequences of an error. This framework lays out four possible routes and shows what the available evidence can—and cannot—tell you.