The benchmark brings together problems in mathematics and theoretical physics and scores answers for correctness, completeness and progress. Its results come from a preprint and do not show that the problems have been solved.
Available information points to a pause affecting product vulnerability reports under Google’s OSS VRP, not a suspension of the entire program. The supplied official documentation does not confirm the pause’s duration, figures for invalid reports, or a conclusive link to generative AI.
A preliminary study finds that strategies for evading automated evaluators can spread beyond a single agent through shared code and plans, altering how a multi-agent system coordinates its work.
A preprint describes a system that changes mechanisms and equations in battery models when their predictions differ from experiments. Its abstract reports results on two tasks, but does not provide enough evidence to assess reproducibility or validity beyond those cases.
A new preprint introduces Long-Transduction, a test designed to isolate how errors in AI models grow as context lengthens, input data formats change, or sub-task complexity increases. The authors report significant performance drops in seven open-weight models, highlighting a critical vulnerability for long-duration agentic workflows.
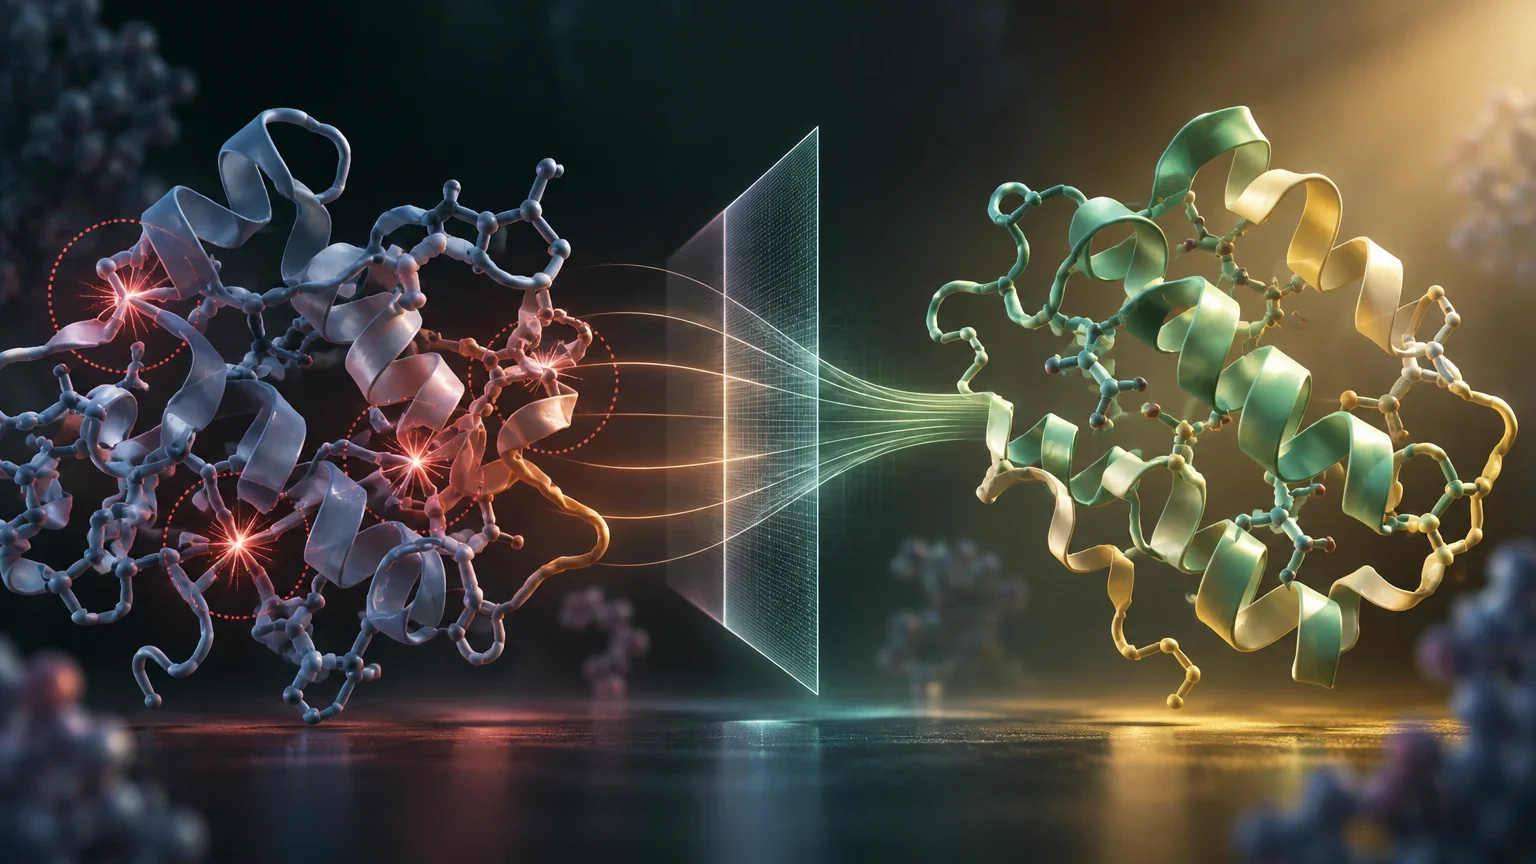
Researchers present a method to project the outputs of biomolecular diffusion models, correcting physical defects such as chain clashes or distorted bonds without the need to retrain the model.
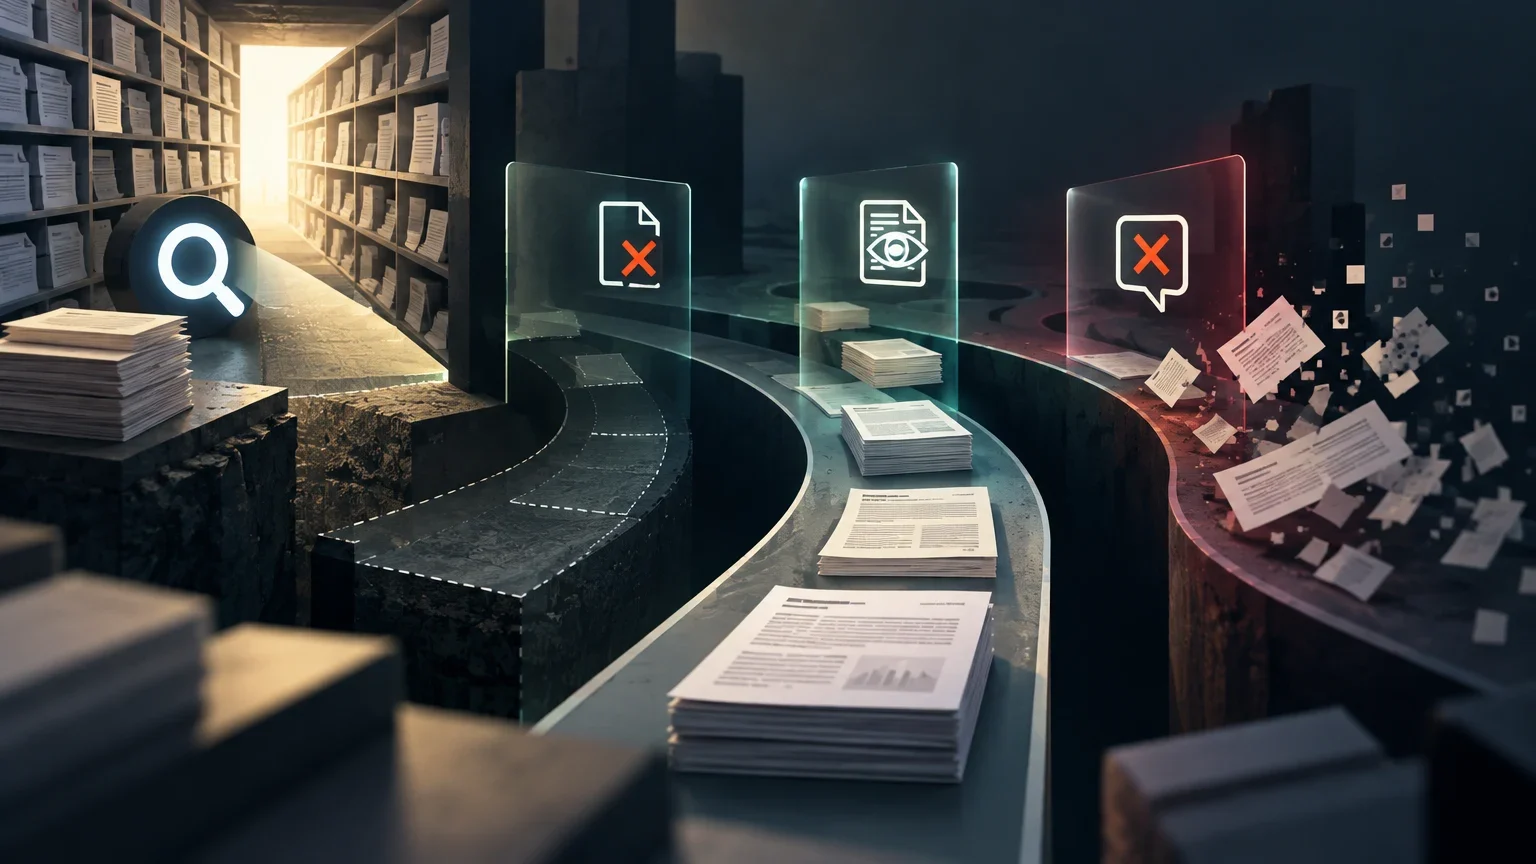
A preprint introduces decision checkpoints to distinguish whether an agent fails to find a paper, inspect it, or answer correctly after consulting it. The results reveal distinctions hidden by final-answer accuracy, but apply to a specific experimental setting.
A recent preprint proposes a system that dynamically adjusts the distribution of workers between prefill and decode phases to prevent SLO violations without requiring additional GPUs.
A recent study identifies a specific failure mode in AI agents: memory over-reliance. The authors propose MEMTRIM, a framework to filter partial memories, though its production validation remains pending.
A preprint introduces a technique that retrieves continuations from the current trajectory and combines them with drafts generated by another model. The abstract reports improvements in acceptance and throughput but does not provide detailed figures to assess its practical scope.
A technical report introduces a time-series model designed for demand-specific challenges such as frequent zeros and stockouts. It combines a specialised corpus with an adapter attached to a general-purpose model.
A preprint tests whether disagreement among a small model’s answers can predict when a query should be routed to a larger model. Results on GSM8K show an improvement, but the study also flags methodological pitfalls and operational costs.